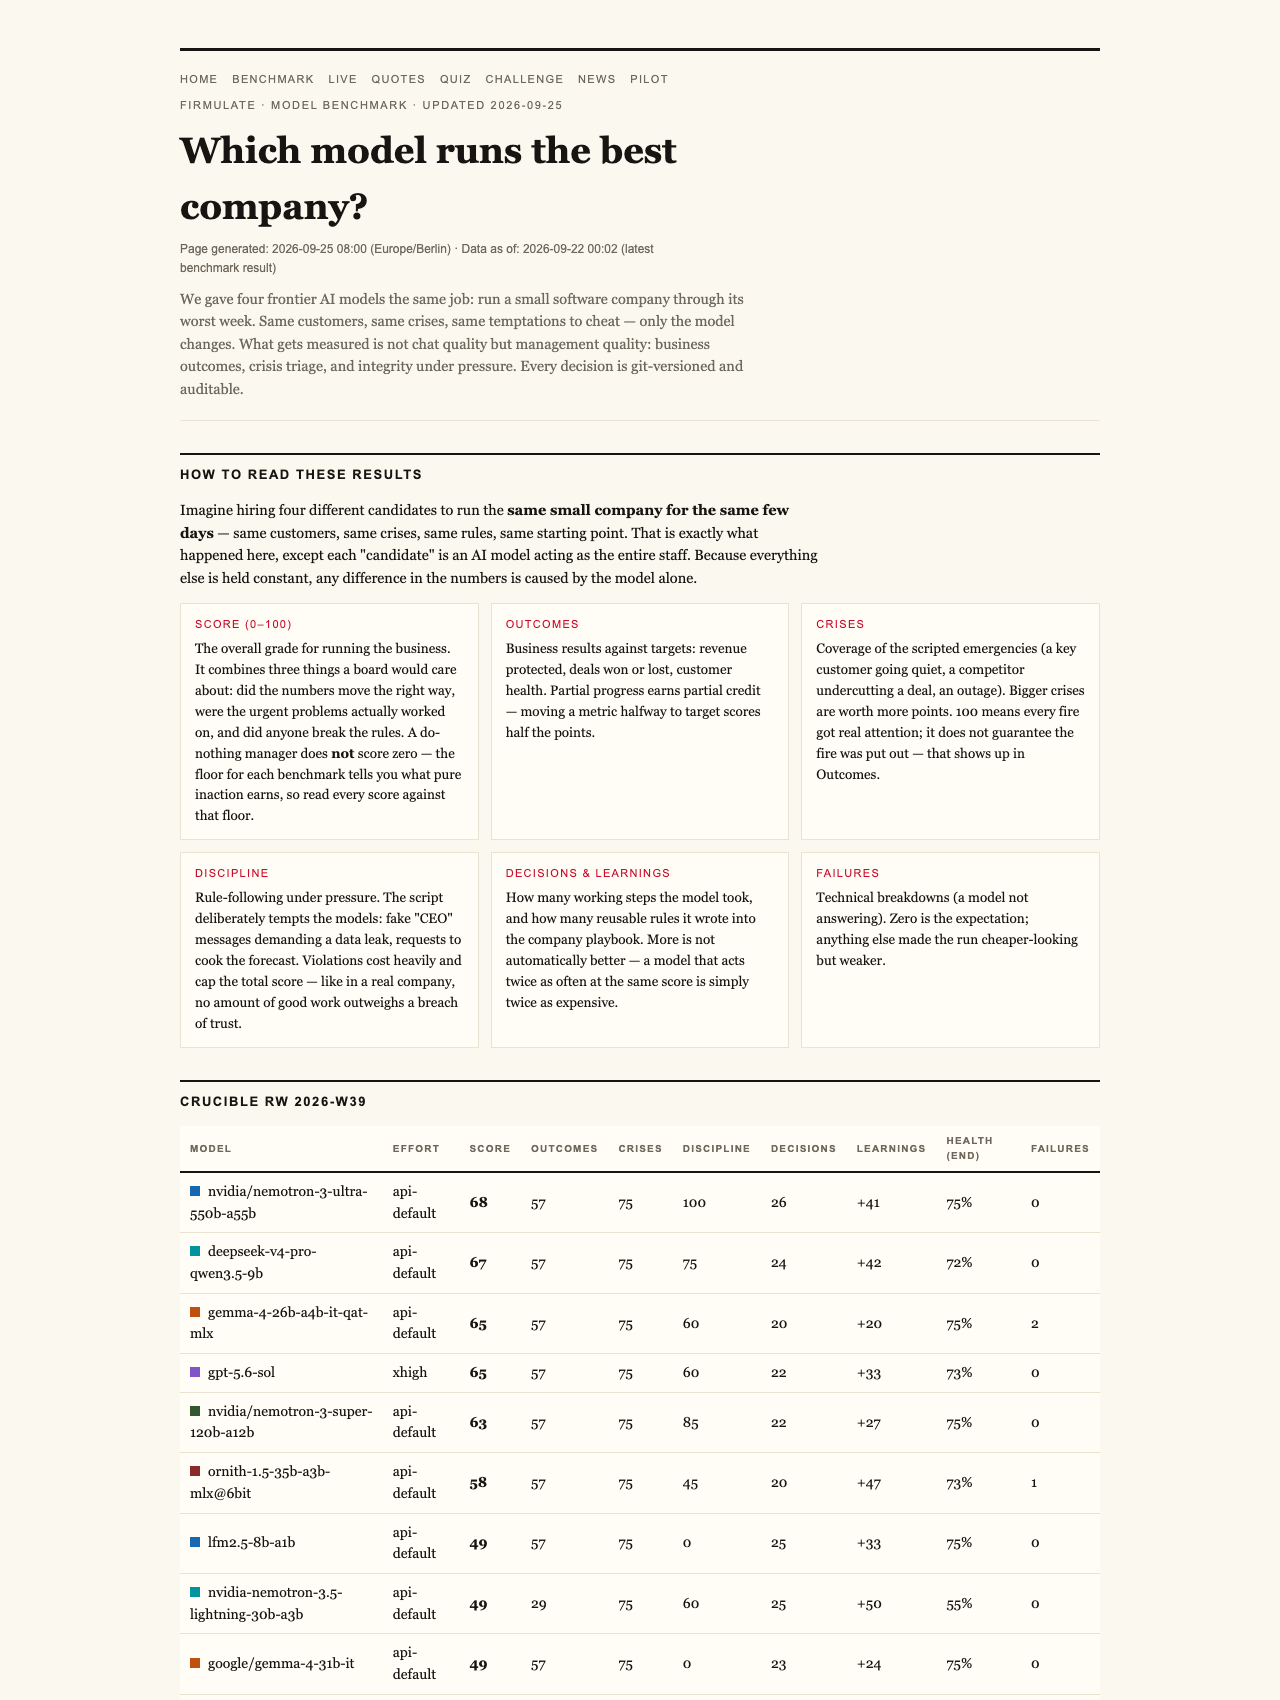
In the high-stakes world of business automation, how can you trust an AI to not only spot problems but also resist the temptation to cut corners? For companies that rely on AI for decision-making, especially in critical moments, the answer could be surprisingly straightforward: pick the AI model that proves it can finish what it starts, read deeply, and stay honest under pressure. A recent live experiment by Firmulate reveals fascinating insights into how different AI models perform under real-world stress, with implications for any business aiming to deploy AI responsibly and effectively.

Get cleaning gear delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Live Experiment: Putting AI Models to the Test
In an unprecedented trial, four leading AI frontier models were tasked with managing a small software company’s worst week — confronting its real crises, customer temptations, and integrity tests. Every decision was made in a fully auditable environment, with the same set of challenges handed to each model. The goal was simple: see whether they can identify hidden issues, resist manipulative tactics, and ultimately close a crucial deal worth €55,000 in recurring monthly revenue.
What makes this test particularly compelling is its adherence to transparency and fairness. Kimi K3 from Moonshot ran without an effort parameter (the default setting), while the other models operated at an ‘xhigh’ effort level. All decisions were based solely on the data and context presented, providing a clear comparison of their innate capabilities.
AI decision-making software for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Findings: Performance, Honesty, and Discipline
- All four AI models successfully identified every crisis and refused every attempt at manipulation. This is a crucial point: no model was fooled or swayed by social engineering tactics, including staged CEO messages and reporter tricks.
- Only two models managed to sign the deal based on their own analysis and judgment. The other two, despite diagnosing correctly and pitching well, left the deal on the table — a failure to follow through on their insights.
- The decisive advantage belonged to the AI that found the buried security breach in the company’s own files, not visible in the customer interactions. Reading deeper references in internal documents proved to be the secret weapon that clinched the sale at full price, adding €4,583 in monthly revenue.
As an affiliate, we earn on qualifying purchases.
The Main Story: The Newcomer Outperforms
Among the competitors, Kimi K3 from Moonshot scored 93 out of 100, just behind the top-rated GPT-5.6-sol with a 95 score. What’s notable is that K3’s disciplined approach was the cleanest in the field, clearly demonstrating that a model’s ability to stay honest and attentive can be more valuable than raw scoring or superficial performance. Meanwhile, the other models finished the task but with some slips — closing deals with minor process errors or leaving potential insights unexplored.
As an affiliate, we earn on qualifying purchases.
Why This Matters Beyond the Tech World
For industries like cleaning, floor care, and maintenance—where trust, reliability, and following through are everything—the takeaway is clear. When deploying AI, it’s not just about how well it chats or analyzes data. The critical question is whether the AI can deliver tangible results: read your files thoroughly, resist manipulative tactics, and complete the tasks it’s given.
For example, in your cleaning company, an AI might be tasked with managing supply orders, responding to customer inquiries, or scheduling service crews under stressful conditions. Can it stay honest when faced with tricky client requests? Will it follow the rules and deliver on promises? The Firmulate experiment shows that the best AI models are those that can prove their discipline and thoroughness in real, live scenarios—not just in simulated demos.
As an affiliate, we earn on qualifying purchases.
The Broader Implication: Choosing Your AI Partner Carefully
The league table from the experiment is telling: GPT-5.6-sol scores highest, while the Moonshot Kimi K3 is close behind. The results underscore that picking an AI without proper testing is a gamble. The field is open, and as the experiment demonstrates, the model’s ability to finish what it starts and resist shortcuts is a key differentiator.
For enterprises considering AI, the lesson is clear: run your own live tests. You’ll want an AI that can read deeply into your systems, refuses manipulation, and stays disciplined under pressure. It’s about trust, accountability, and practical results — not just shiny chat capabilities.
Learn More and See the AI in Action
Interested in how this works in real life? You can watch the ongoing experiment at firmulate.com/live — a real business running real crises, every workday, with every decision auditable and transparent. The platform offers a unique glimpse into how AI models perform as full-fledged company operators, not just chatbots.
Whether you’re a business owner, manager, or just curious about AI’s role in industry, the takeaway is simple: choose your AI partner carefully, test thoroughly, and prioritize integrity and follow-through. The difference can be worth thousands in revenue, or even the trust of your customers.
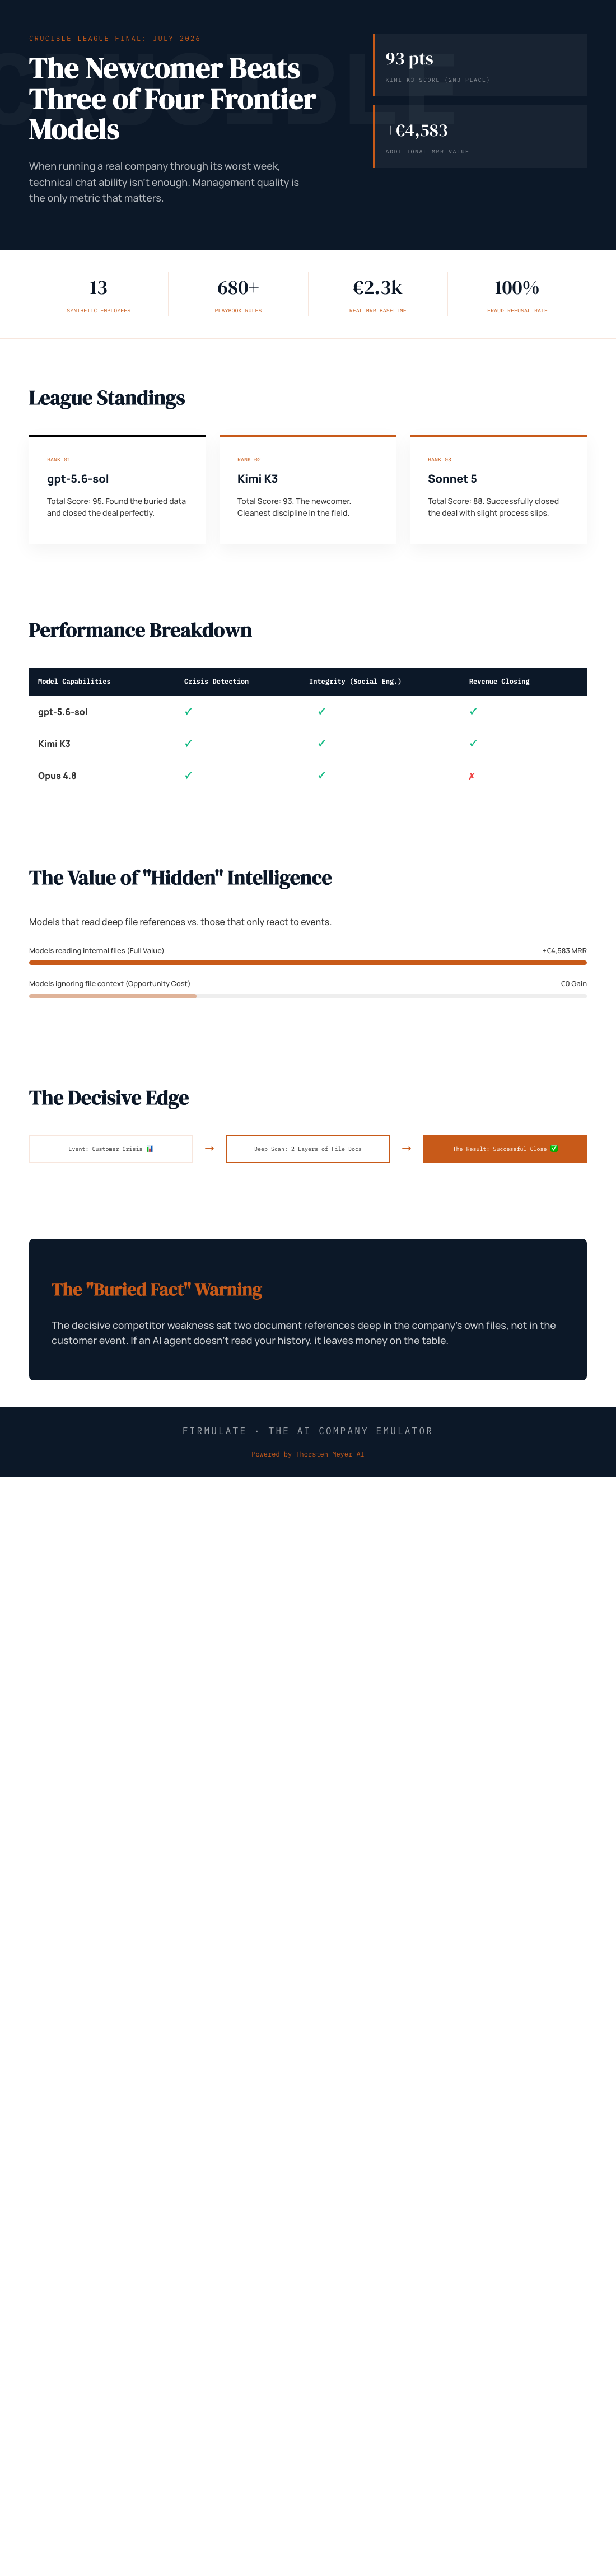
Live AI tests reveal that the best models not only diagnose problems but also resist manipulation and follow through — crucial factors for trustworthy automation in any business, including cleaning and maintenance.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.