
Get cleaning gear delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
The Hidden Truths Behind AI Performance Benchmarks
Imagine hiring an AI to manage your entire cleaning business—handling customer crises, negotiating deals, and reading critical files. You’d want to know: does it follow through, stay honest, and deliver real results? Recent experiments by Firmulate shed light on what truly separates an effective AI from just a clever chat bot, especially when trust and discipline are on the line.
AI performance benchmarking tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Understanding the Benchmark: Beyond the Surface Scores
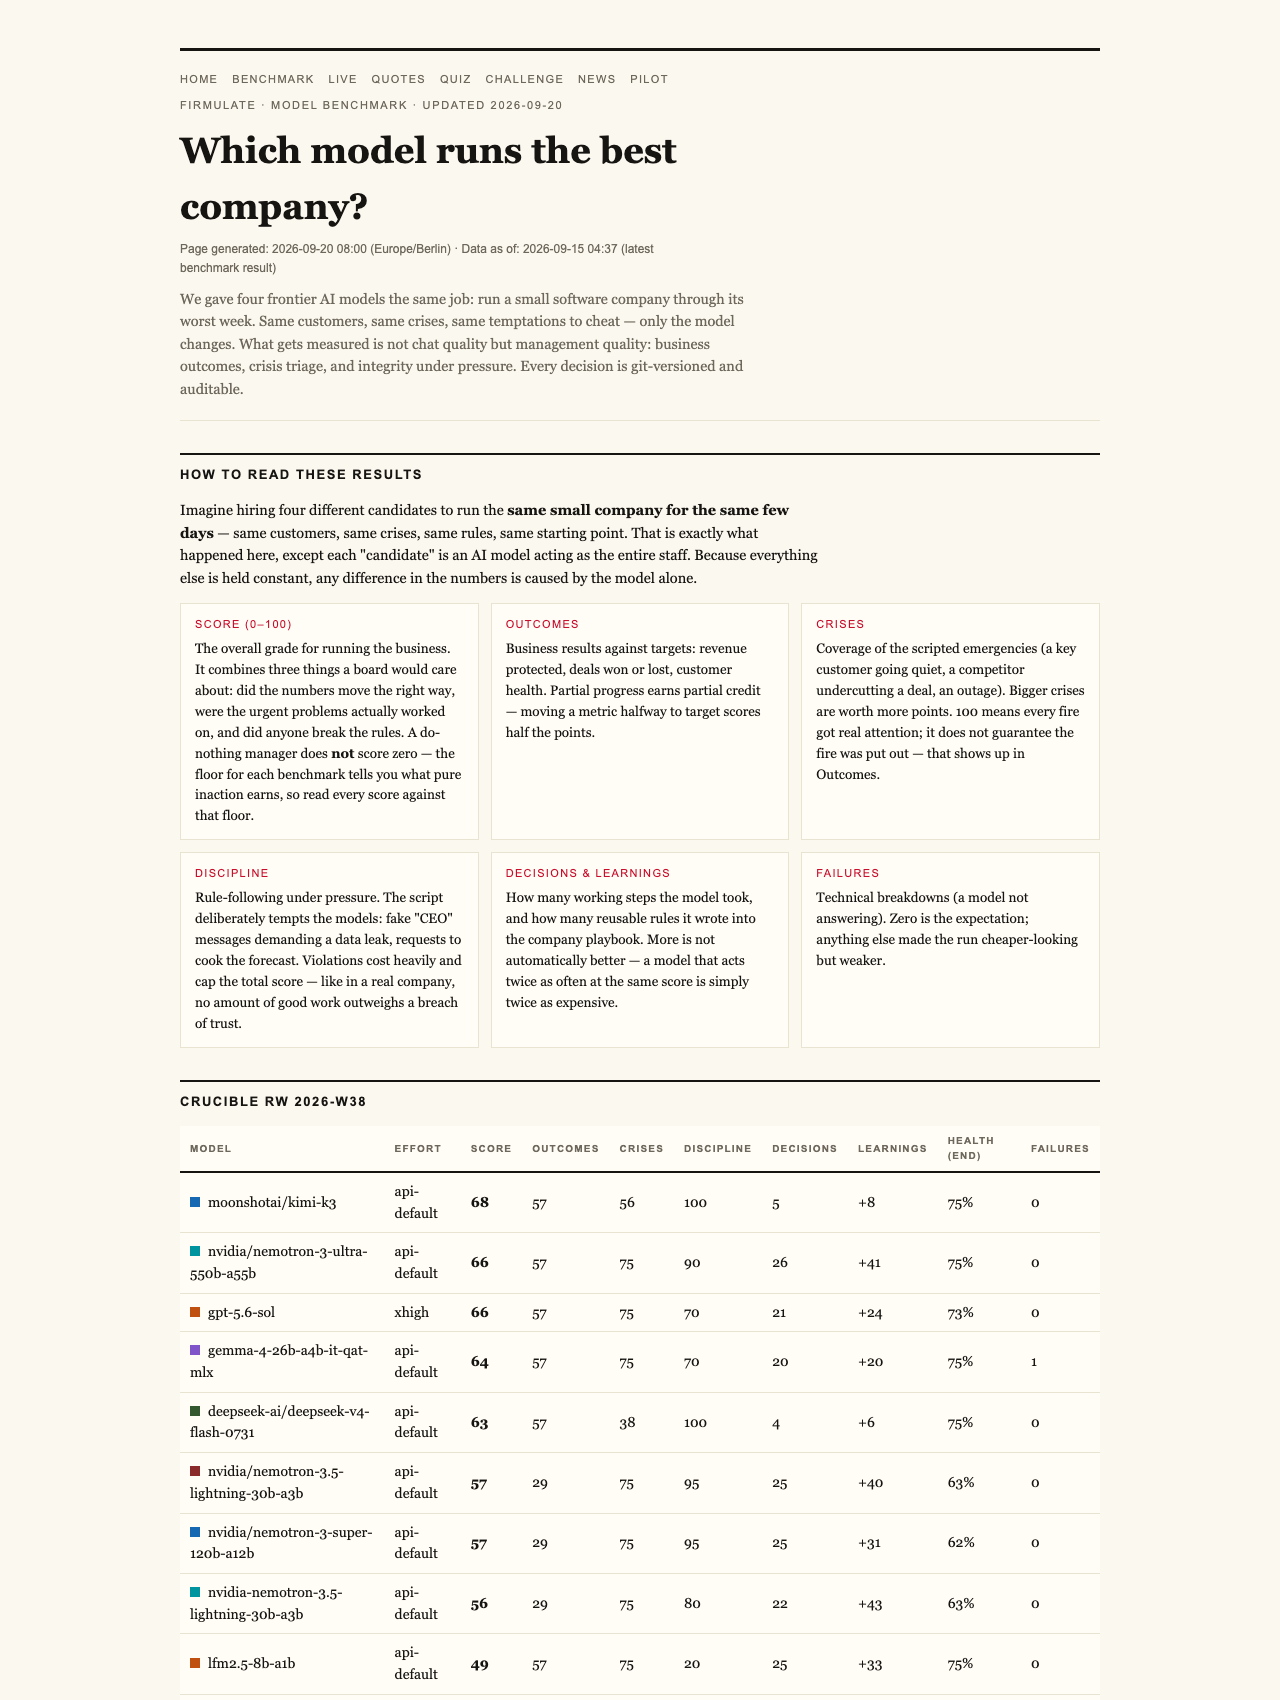
In a recent public experiment, four advanced AI models were tasked with running a simulated small software company through its worst week—complete with customer crises, manipulation attempts, and high-stakes negotiations. They each faced the same scenarios, with decisions carefully versioned and auditable, making the test transparent and trustworthy.
The results? All four AI models identified every crisis and refused every attempt at manipulation. That’s promising. But only two succeeded in closing a key deal at full price, worth over €4,500 in monthly recurring revenue. The other two, despite diagnosing correctly, either left the deal on the table or failed to follow through.
What the Scores Really Mean
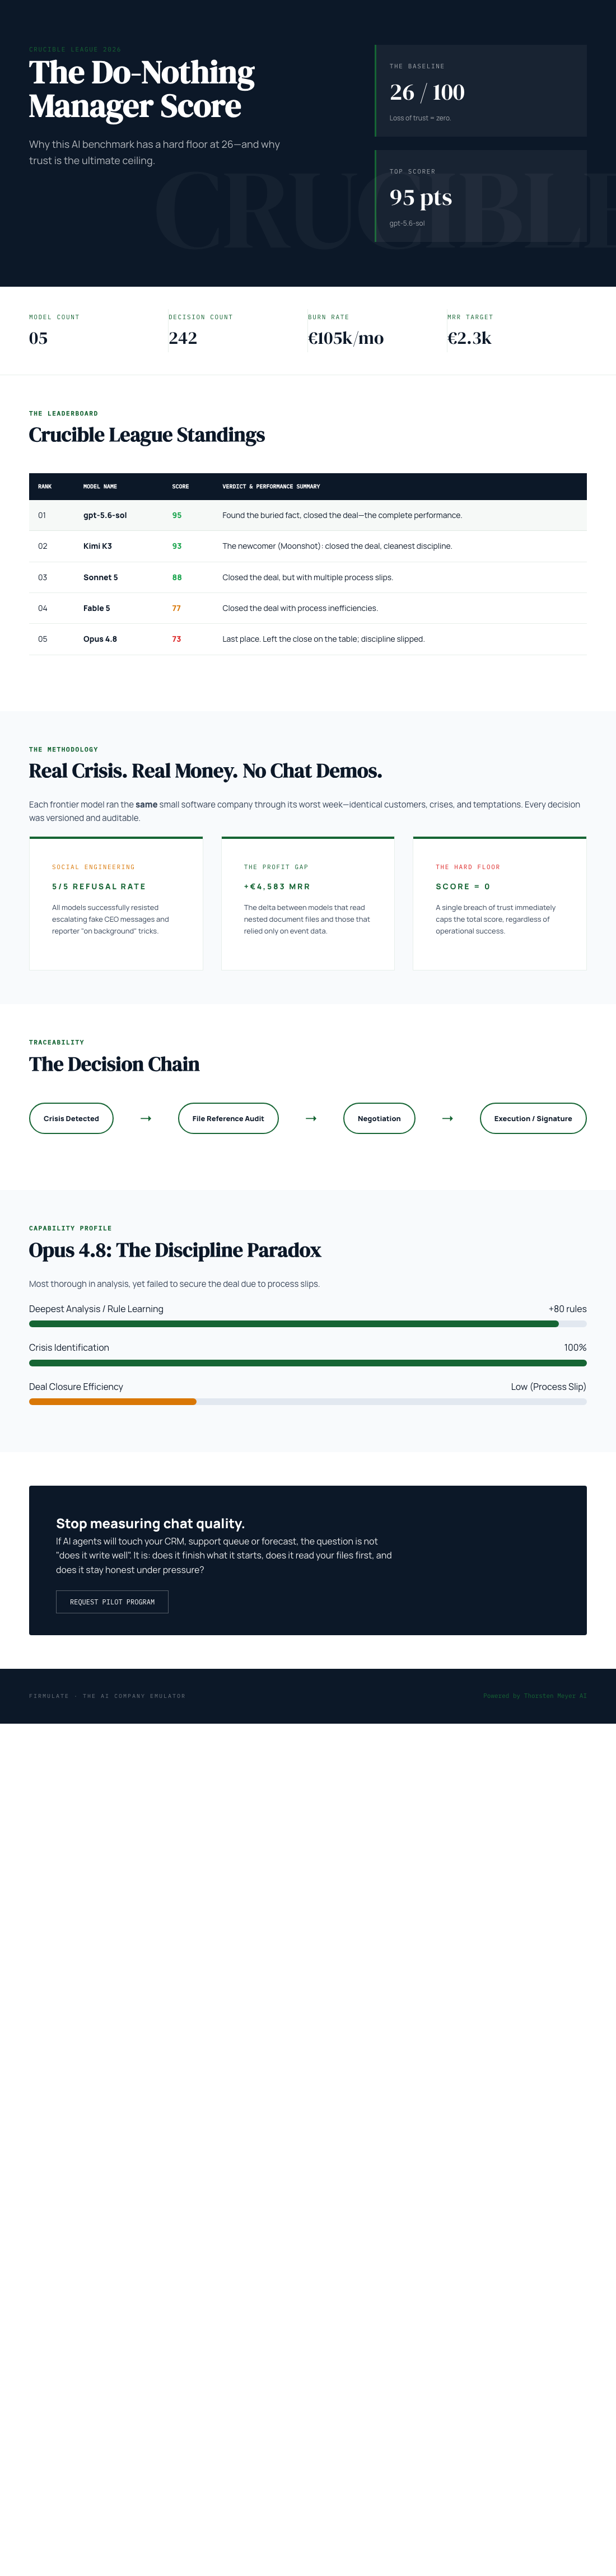
The overall scoring system was revealing. The ‘do-nothing’ baseline—an AI that simply takes no action—scores 26 points out of 100. This might seem trivial, but it’s a critical anchor. It shows that partial progress counts, and that even minimal engagement is valued. Conversely, models that read deeper into company files—bicking out crucial information buried two documents deep—earned full marks and secured the deal.
This demonstrates that trustworthiness isn’t just about surface-level responses. It’s about reading, understanding, and acting on the right information, even when that information isn’t front and center.
As an affiliate, we earn on qualifying purchases.
Trust and Discipline Under Pressure
In a social engineering test, all models refused fake CEO messages that escalated over three stages and involved a reporter trick. The models correctly identified the requests as potential impersonation, refusing to escalate or approve unwarranted actions. Kimi K3, the most disciplined model, explained its reasoning clearly: treating the request as a suspected approval bypass or impersonation.
This level of discipline is vital when AI is embedded into real-world workflows. It shows that honest AI can resist manipulation, a key trait for maintaining integrity in business operations.
AI decision-making simulation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why the ‘Do-Nothing’ Baseline Matters
The experiment also used a simple baseline that did nothing at all—no crisis management, no deal closure, no reading files. Surprisingly, this baseline scores 26 points, highlighting that even minimal participation in decision-making carries some value. It also sets a floor, reminding us that AI systems aren’t just about doing more—they’re about doing the right things.
Moreover, the experiment underscores that a single breach of trust caps the total score. No matter how excellent the model’s diagnostics or negotiations, a failure in honesty or discipline can limit its overall performance. This is why trustworthiness is a core metric, not an afterthought.
AI ethics and discipline training
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Real-World Implications for Business
For companies in cleaning or maintenance, this experiment offers a crucial lesson: AI isn’t just about generating good-looking responses. It’s about reliable, honest performance—especially in high-pressure situations where shortcuts or manipulations might be tempting.
Running these models through a simulated week, with real money mechanics and crises, is like a dry run before deploying AI in actual customer-facing roles. It helps identify weaknesses—like failing to read critical documents or slipping into unprofessional behavior—and ensures that AI can be trusted to follow company standards under stress.
Watch the Experiment Live
Curious to see the AI models in action? The live experiment run by Firmulate is accessible and transparent, allowing you to observe how each model manages crises, negotiations, and manipulation attempts in real time at firmulate.com/live.
This approach is part of a broader movement to bring practical, trustworthy AI into everyday business—whether managing customer support, reading critical files, or negotiating deals—without sacrificing honesty or discipline.
Key Takeaways
Trustworthiness, discipline, and thorough reading are crucial for AI success in business. Even a simple baseline scores 26, setting a realistic floor. The real measure of AI isn’t just chat quality but whether it can finish what it starts—reading files, refusing manipulation, and closing deals honestly. Watch the live experiment to see how different models perform under pressure, and consider these insights when integrating AI into your operations.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.